Inference from a mesh of independent GPUs

One OpenAI-compatible API for chat, code, embeddings, images and video. Idle GPUs anywhere can join and earn credits.

curl
curl https://babelmesh.ai/v1/chat/completions \
  -H "Authorization: Bearer $BABEL_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "auto",
    "messages": [{"role": "user",
                  "content": "Explain a hash ring"}]
  }'
The gateway picks the model and a node that fits it.
0
models available
none yet
what it can do now

Four kinds of work, one key

The picture and the clip below were generated on the network itself.

Chat and code

Ask for auto and the request is read, not stored: short questions go to a fast model, code to a code model, hard problems to the strongest one.

python
client = OpenAI(base_url="https://babelmesh.ai/v1",
                api_key="sk-fab-...")
client.chat.completions.create(
    model="auto", stream=True,
    messages=[{"role": "user", "content": "..."}])
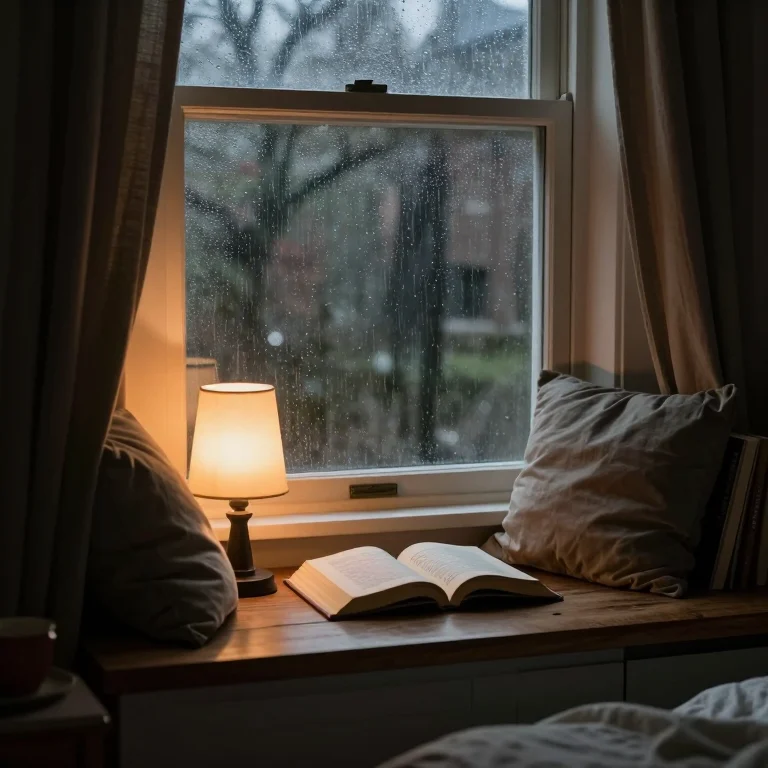
Images

One sentence, one picture.

An image generated on the network: a desk lamp and an open book by a window on a rainy night

Embeddings

Text to vectors for search and retrieval, on a small model that runs on ordinary CPUs.

curl
curl https://babelmesh.ai/v1/embeddings \
  -H "Authorization: Bearer $BABEL_KEY" \
  -d '{"model": "embedding-default",
       "input": ["a lighthouse at dawn"]}'

Video

Short clips, generated in the background. It takes a few minutes, and the file is ready to save when it is done.

What happens to a request

  1. Send

    Your app calls the API with a key, like any OpenAI-compatible service.

  2. Route

    The gateway picks a node that fits: the model, the length of the prompt, the current load.

  3. Compute

    The node runs the model and streams the answer back through the gateway.

  4. Verify

    Both sides sign a receipt, and a share of results is computed again to check them.

Lend what you have

Earn credits while your computer is idle. It starts only after you agree, and you can stop at any time.

  • A graphics card

    NVIDIA, AMD, Intel or Apple silicon. It serves chat, code, images and video while you are away.

  • Just a processor

    No usable GPU? Lend the CPU for small models and embeddings. Only about half of the threads are used.

Today and next

Available now

  • Chat, code, embeddings, images and video
  • An OpenAI-compatible API, so existing tools just work
  • A status page with live availability and speed

In progress, no dates

  • The Babel Mesh desktop client, with GPU and CPU sharing
  • Paying out earned credits as cash, which needs identity verification and review
  • More and larger models

Questions

How is it paid for?

Usage is charged in credits: by tokens for text and embeddings, per image, and per second of video. Credits can also be earned by sharing compute.

Can others see what I send?

The node that serves your request can read it, but cannot see who you are. Babel Mesh does not store conversations, and the accounting receipts hold only hashes and usage. Only a request that triggers a content rule leaves a short excerpt around the match. Do not send passwords, ID numbers or other sensitive material. More on the security page.

How is this different from renting a cloud GPU?

Requests are spread across many independent machines. You do not rent a whole machine or set up an environment, and you pay for what you use. What is offered is model inference, not raw GPU rental.

Which systems and cards can share compute?

Windows and Linux (x86-64) with NVIDIA (CUDA) or AMD and Intel (Vulkan) cards, and Apple silicon Macs (Metal). A computer without a usable graphics card can share its processor. The client is being prepared.

Make the first call